Senior Site Reliability Engineer (SRE)
Shrnutí práce
Plný úvazek
Paris
Několik dní doma
Plat: 70K až 75K €
Dovednosti a odbornost
Infrastructure as Code (IaC)
Grafana
MariaDB
GitLab CI
Kubernetes
+6
Otázky a odpovědi ohledně nabídky
Pozice
Popis pozice
About us
💙 Implicity is a digital MedTech, that brings outstanding innovations to cardiologists, thanks to Big Data and Artificial Intelligence.
Thanks to our leading cardiac remote monitoring platform, it is way easier to manage data and predict patient issues, so that cardiologists can bring the best care at the best time.
To put it simply, when you join Implicity, you will contribute to save lives with us 💓🩺
Dr Arnaud Rosier (cardiologist and AI researcher) & David Perlmutter (engineer and entrepreneur), co-founded Implicity in 2016.
10+ years later, a French Start-Up / Scale-Up 🐓 is a real game changer in the healthcare market, literally shaping the future of cardiology.
250+ hospitals / medical centers are already using our solutions, covering 100 000+ patients.
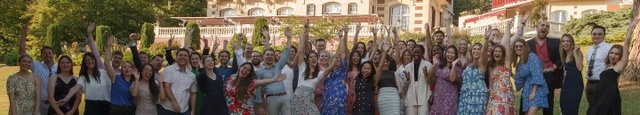
👩🏻👨🏿👱🏻 At Implicity, you will find the greatest experts in data science, engineering, clinical, regulatory, IT, sales, customers success, etc. working together.
This amazing team already managed to make Implicity a clear European leader, and we will very soon do the same in the US market.
In a nutshell, thanks to Implicity:
🏆 Patients get a far better care
🏆 Doctors’ life is far easier, they can have a far better focus on prevention/treatment, and not admin/data burden
🏆 Healthcare payers (Social Security in France) eventually pays a far lower price (preventing/monitoring instead of treating/hospitalizing)
The team
You will join the Infra/Platform team: four engineers led by Cyrille, our DevOps & Infrastructure Engineering Manager. They own the entire infrastructure and the stability of the platform, and they are the go-to technical partner for every team at Implicity, tech and non-tech alike. The team works in Kanban, with a quarterly view on the projects other teams bring us, plus a daily stand-up and weekly 1:1s.
Why this role matters
We are moving from a team that reacts to requests to a team that provides a real service to the rest of the company. Our infrastructure was designed in 2017, and with scale-up and the US market as priorities, 2027 is a year of transformation. We are looking for a senior engineer who has seen production get rough, keeps a cool head when it does, and wants to help reshape the platform.
What you will do
Build, evolve and maintain our cloud infrastructure as code (Terraform on AWS)
Own and improve CI/CD, automation, observability and monitoring
Keep the platform stable: take part in run activities, handle incidents and drive post-incident improvements
Act as a technical reference for other teams: assess new technologies, validate technical choices and integrate new building blocks
Take an active part in our 2027 projects: Terraform refactoring, Kubernetes and containerization overhaul, a move to multi-cloud, and a fresh look at our core stack (MariaDB, RabbitMQ…)
What we are looking for
Significant experience in infrastructure / ops / SRE, ideally with a background that goes beyond cloud (e.g. sysadmin who grew into cloud)
Real production run experience: on-call, critical incidents, and the ability to stay calm and structured under pressure
Solid hands-on experience with AWS in production
Infrastructure as Code with Terraform
CI pipelines (GitLab CI, GitHub Actions or similar)
Willingness to work on GCP as we move to multi-cloud
Fluent English; French is a strong plus
Nice to have
Flux or another GitOps tool, Kubernetes
Deep experience with observability (Grafana, Prometheus…)
FinOps / cloud cost optimization
Experience in a company serving the US or international markets
Experience in a regulated environment (healthcare, finance…)
Who you are
You say things as they are: you raise problems early and constructively instead of smoothing them over
You treat other teams as your clients: you listen, you explain, you support
You welcome feedback and challenge yourself
You enjoy transformation projects and like bringing strong, well-argued proposals
You use AI tools as part of how you work
What we offer
Salary: €70–75k gross/year, depending on experience
Based in Paris, hybrid 2 days in the office, 3 days remote
A product with real medical impact and a team in the middle of a transformation
Our hiring process
Call with our Talent team (about 30 min, video conference)
Technical interview with Cyrille, DevOps & Infrastructure Engineering Manager (about 1h30, video conference)
Team meeting (30min) and final interview with the CTO (1h) in person, on-site meetings
Reference check & offer
It can start as soon as you can!
Chcete se dozvědět více?
Rencontrez Louay, CTO
Meet Julien SARAZIN, Software architect
Tato volná pracovní místa by vás mohla zajímat!
Tyto společnosti rovněž nabírají pracovníky na pozici "{profese}".
Staff Site Reliability Engineer (x/f/m)
DoctolibPlný úvazekParisNěkolik dní domaMobile Apps, Software3 000 zaměstnanciLead Site Reliability Engineer (SRE)
amoPlný úvazekParisŽádná práce na dálkuMobile Apps, Software59 zaměstnanciDevOps / Infra Lead
PayflowsPlný úvazekParisNěkolik dní domaPlat: 75K až 95K €Software, Artificial Intelligence / Machine Learning35 zaměstnanciDevOps Engineer
SkaleetPlný úvazekBoulogne-BillancourtPříležitostná práce z domovaSoftware, IT / Digital120 zaměstnanciSenior Cloud Infrastructure Engineer
InatoPlný úvazekParisPlně vzdálenýPlat: 70K až 90K €Software, Farmacie/ Biotechnologie70 zaměstnanci